On HO-Cap, a public hand-object dataset, we scored 3D hands on each of 8 people (64 sequences) with models trained only on the other seven. Errors are absolute 3D positions with no alignment to the reference. Off-the-shelf MediaPipe keypoints, tracked and smoothed, gave a median joint error of 9.9 mm with 8 cameras. A learned 3D correction toward joint centres brought that to 6.2 mm, and our own 2D keypoint refiner to 5.4 mm. With 4 cameras the same steps gave 10.8, 7.2 and 5.6 mm. Per person the full pipeline ranged from 4.3 to 6.5 mm with 8 cameras and 4.2 to 8.0 mm with 4. Fingertips: 7.0 mm with either camera count. Most of the gain comes from correcting for detectors marking the skin while robot hand models use joint centres.
01What we measured
HO-Cap records people picking up and using everyday objects in a lab, filmed by 8 fixed colour cameras at 640×480 and 30 fps, plus a head-mounted camera. It ships 3D hand joints for every frame and is released under CC BY 4.0 (Wang et al., “HO-Cap: A Capture System and Dataset for 3D Reconstruction and Pose Tracking of Hand-Object Interaction,” NeurIPS 2025 Datasets and Benchmarks Track (paper)). We grouped its 64 sequences by person, which gives 8 people, and ran leave-one-person-out: for each person, every learned part of our pipeline was trained on the other seven and then scored on that person alone. The reference labels are used only for training and scoring; at run time the pipeline sees only the camera images and calibration.
The score is the distance between our 3D joints and HO-Cap’s, over all 21 joints of each hand. Errors are absolute positions in the camera rig’s world frame, with no alignment to the reference, so wrist position counts too. Many published hand-pose numbers are reported after aligning each hand to the ground truth, which removes that part of the error, so compare with care. We report the median per person, then the median over people. We ran everything twice: with all 8 cameras, and with 4 of them. The 4 were picked per sequence as the cameras where the detector found hands most often, without looking at the reference labels.
02Results
Median 3D hand-joint error on people left out of training
8 cameras
4 cameras
Each step helps at both camera counts. The refiner closes most of the gap between them: 1.0 mm before it, 0.2 mm after. With it, 4 cameras (5.6 mm) beat 8 cameras without it (6.2 mm). Fingertips, which matter most for grasping, go from 11.6 mm to 7.0 mm with 8 cameras, and reach 7.0 mm with 4. The full pipeline’s per-person results:
| Person | Sequences | 8 cams, off-the-shelf | 8 cams, ours | 8 cams, ours p90 | 4 cams, ours | 2D error before → after |
|---|---|---|---|---|---|---|
| A | 7 | 11.1 mm | 5.9 mm | 12.0 mm | 6.8 mm | 6.7 → 3.9 px |
| B | 18 | 10.3 mm | 5.3 mm | 10.8 mm | 5.7 mm | 6.3 → 3.9 px |
| C | 11 | 9.1 mm | 4.4 mm | 9.6 mm | 4.2 mm | 5.0 → 2.8 px |
| D | 3 | 9.6 mm | 5.5 mm | 12.4 mm | 5.4 mm | 6.6 → 3.5 px |
| E | 7 | 8.7 mm | 4.8 mm | 10.5 mm | 4.9 mm | 6.0 → 3.7 px |
| F | 7 | 11.2 mm | 6.5 mm | 13.3 mm | 8.0 mm | 6.9 → 4.9 px |
| G | 4 | 11.2 mm | 5.8 mm | 13.0 mm | 6.5 mm | 7.0 → 3.9 px |
| H | 7 | 9.5 mm | 4.3 mm | 8.7 mm | 4.6 mm | 5.9 → 3.1 px |
The p90 column is the error that 90% of joints stay under. The 2D column is keypoint error inside 128-pixel hand crops, before and after our refiner; it falls by about 40% at the median, and by 29–47% per person. Person F is the weakest, at 6.5 mm with 8 cameras and 8.0 mm with 4.
03Skin keypoints and joint centres
Off-the-shelf hand detectors such as MediaPipe are trained on images labelled by people, who click on the visible surface of the hand. A robot hand model, a physics simulator and a dataset like HO-Cap all describe the hand by its joint centres, which sit inside the finger. At the knuckles the two differ by 15–21 mm on HO-Cap. Triangulating skin points perfectly still leaves that offset, which is why our first versions stalled at about 11 mm no matter how many cameras we added.
The first fix works in 3D: a learned correction moves each triangulated point toward its joint centre. Trained on one person it carried over less well to others; trained on seven it brought held-out people from 9.9 to 6.2 mm with 8 cameras.
04Why several cameras
From one camera, how far away a finger is has to be guessed. With two or more calibrated cameras each joint is triangulated, so depth comes from geometry. More views also mean that when an object hides a finger from one camera, another usually sees it, and one bad detection does not have to drag the whole hand.
05Tracking over time
Detectors miss small or partly hidden hands in a full frame. The pipeline uses all the cameras together to recover hands a single view missed, which lowered error by about 1 mm, follows each hand over time so left and right stay consistent without any ground truth, and removes most of the frame-to-frame jitter.
06Our 2D keypoint refiner
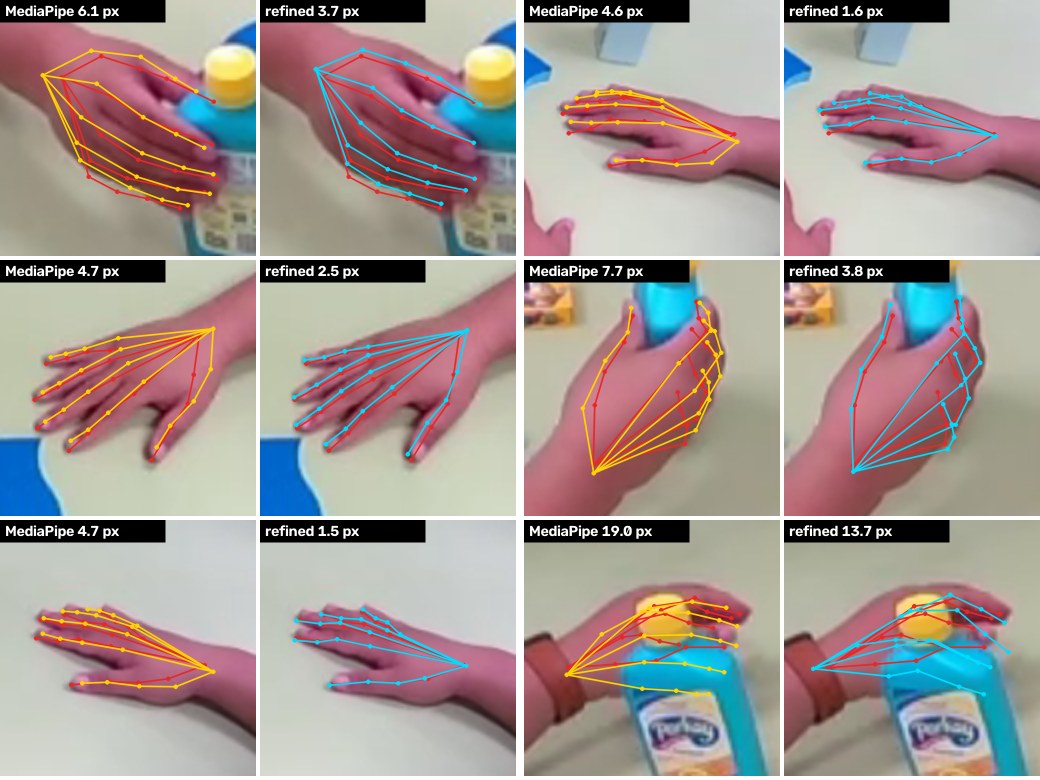
The 3D correction can only adjust what the cameras reported. The refiner is our own learned model that fixes the 2D keypoints in each camera before triangulation, moving each point from where the off-the-shelf detector put it toward the joint centre. Like every learned part of the pipeline, it was trained only on the other seven people each time.
07Checking head-camera hand labels
Hands leave the head camera’s frame, overlap and blur when the head turns, so automatic hand labels in first-person video drift. Once the outside cameras have a 3D hand, we can check the head camera’s labels against it and flag the frames where they disagree. With 4 outside cameras and the headset’s tracked head pose, the flags catch about two thirds of grossly wrong head-camera labels at about 70% precision, roughly twice a single-camera check. Details, and what the same 3D labels do for training head-camera models, are in Training head-camera hand models with 3D labels from outside cameras.
08Labels without annotators
The refiner learned from HO-Cap’s labels, which are themselves built from many views. Our own captures can produce training labels the same way, for every camera including the head camera, with no one clicking points. Training on those labels should let later captures in similar settings get by with fewer cameras. We have not yet measured this beyond HO-Cap.
09Limits
- HO-Cap’s cameras are 640×480 lab cameras at fixed positions. Phones and head cameras in a real workplace will behave differently.
- The reference labels are not exact. They are fitted from the dataset’s own camera rig rather than markers, so part of the remaining 5 mm may be theirs.
- Fingers hidden behind an object are the main failure. The refiner helps less there, as the bottle grasp above shows.
- Eight people is a small group. Results varied from 4.3 to 6.5 mm across them with 8 cameras.
- The pipeline’s learned stages were trained one after another on the same seven people, so the later stage saw slightly cleaner inputs in training than it would on new data. The held-out person was never seen.
- Our own captures, a head camera plus phones, are the next test.
10What a capture delivers
- Per frame and per hand: 21 joint centres in millimetres in one world frame, left/right labels; 3D body alongside.
- Per clip: synced video from every camera, camera poses, and an error figure from cameras held out of the reconstruction.
- For first-person data: the frames where head-camera hand labels drift from the outside-camera 3D.
- On request: the motion retargeted to a robot body or robot hand.
Marker-based optical mocap is more precise but needs markers on the hand, which get hidden in grasps; this needs only ordinary cameras around the work area.
Questions
How accurate is markerless multi-camera 3D hand capture?
On the HO-Cap dataset, scored on people left out of training, our pipeline reached a median joint error of 5.4 mm with 8 cameras and 5.6 mm with 4, against 9.9 and 10.8 mm for off-the-shelf keypoints that were tracked and smoothed.
How accurate are MediaPipe hand keypoints in 3D?
Triangulated from 8 cameras and tracked, MediaPipe hand keypoints were 9.9 mm from HO-Cap’s joint centres at the median. Most of that is not noise: detectors mark the visible skin, while robot hand models and 3D datasets use joint centres inside the finger, 15–21 mm apart at the knuckles. Correcting for that brought the error to 5.4 mm.
What does a multi-camera hand capture deliver?
21 joint centres per hand per frame in millimetres in one world frame, left/right labels, the 3D body, synced video and camera poses, an error figure per clip, and on request the motion retargeted to a robot hand or body.
How many cameras do you need for 3D hands?
With our keypoint refiner, 4 cameras gave 5.6 mm on HO-Cap, better than 8 cameras without it (6.2 mm). Fingers hidden behind objects are still the main source of error.