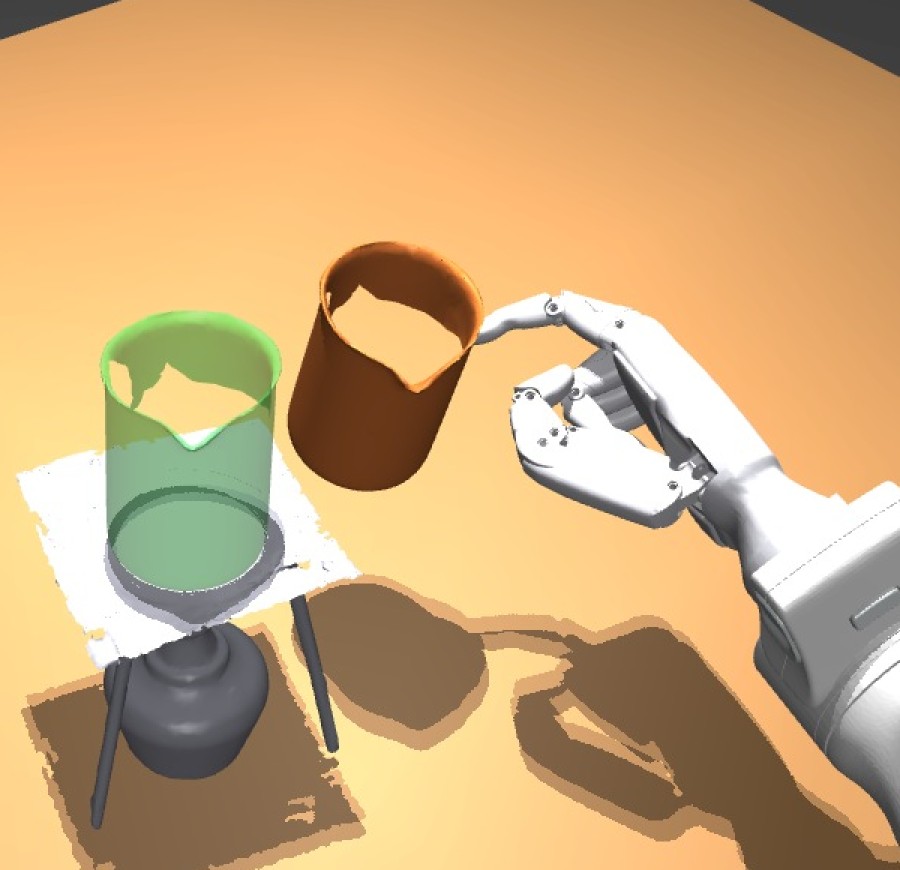
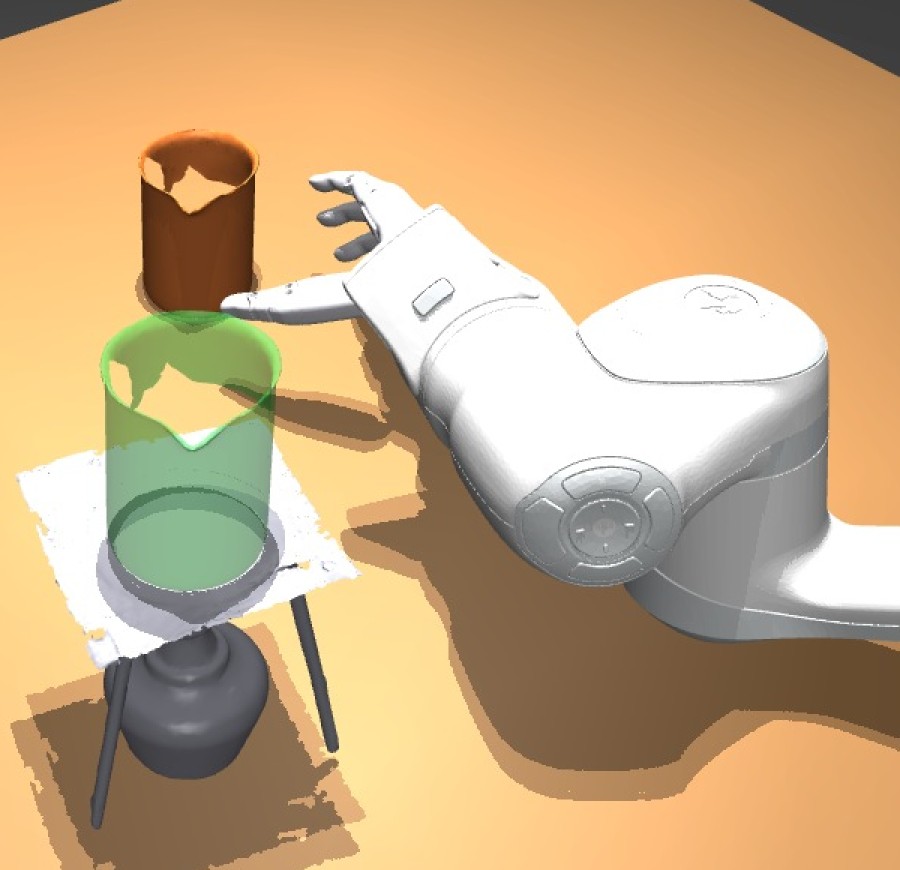
Part 1 scored three fixed cameras and published head-camera methods against OakInk2’s marker motion capture: our cameras place hands 3.0 cm from where they are in the room with no alignment, and head-camera methods given the true camera pose 7.0 to 11.7 cm off. Replayed with a robot hand in a physics replay of 694 episodes, our labels reach a task success of 0.25 against 0.19 from WiLoR’s. This part trains policies on those labels.
In short.
- Policies follow the labels, in simulation. On OakInk2 pick-and-place, scored against motion capture, imitation policies trained on our labels succeed in 0.21 of held-out tests, against 0.08 from WiLoR’s (ours − WiLoR +0.13 [+0.08, +0.18]); with reinforcement learning, 0.41 against 0.24 to 0.28 for head-camera labels.
- Slide: 0.31 from our labels against 0.16 from WiLoR’s (ours − WiLoR +0.15 [+0.09, +0.20]); with reinforcement learning, 0.42 against 0.24.
- Lift-and-return: no clear difference (0.20 from ours, 0.18 from WiLoR’s, +0.02 [−0.08, +0.12]). Both are far below the motion-capture labels (0.36).
- More reinforcement learning does not close the gap. On pick-and-place, at 384 rollouts per episode, ours reaches 0.47 against 0.29 to 0.31 for head-camera labels.
- On HO-Cap reorientation, synthetic demos expanded from a few seed demos did not beat real ones.
What this does to robot policies
A replay follows the labels exactly; a policy learns from them and might average some of the error away. For each label source we built demos by replaying its labels with an Inspire hand on a Franka arm, trained policies on them by imitation and by tracking the labelled motion with a correction learned by reinforcement learning, and tested every policy from the same held-out start poses. Success means the same as in the physics replay in Part 1. OakInk2, scored against marker motion capture, is the independent check and comes first, with three tasks; HO-Cap follows and is partly circular.
Caveats for this whole section.
- HO-Cap is partly circular: its reference is a multi-view fit that shares cameras with ours, which flatters our labels against the head-camera methods. OakInk2’s motion-capture reference has no such link.
- Simulation only, with no real robot; as in the replay, the simulation holds the object once the hand touches it.
- Imitation is roughly capped by the replay: the demos are the robot’s own replays of each source’s labels. The reinforcement-learning results, which get a task signal, are the fairer test of whether learning can undo bad labels.
OakInk2: pick-and-place, against motion capture
On 123 OakInk2 pick-and-place episodes, imitation policies trained on our labels succeed in 0.21 of held-out tests, against 0.03 to 0.12 for head-camera labels (MediaPipe to HaWoR; ours − WiLoR +0.13, 95% CI [+0.08, +0.18]); the motion-capture labels reach 0.29 and the combination of our placement with the head camera’s hand shape 0.23. With tracking and reinforcement learning, ours reaches 0.41 against 0.24 to 0.28 for head-camera labels and 0.46 for motion capture.
imitationtracking + reinforcement learning95% confidence interval
| Labels | error (mm) | imitation | tracking + RL | ours − this |
|---|---|---|---|---|
| Reference | – | 0.29 | 0.46 | −0.09 [−0.14, −0.03] |
| Ours | 28 | 0.21 | 0.41 | – |
| Combination | 36 | 0.23 | 0.39 | −0.02 [−0.06, +0.03] |
| WiLoR | 73 | 0.08 | 0.25 | +0.13 [+0.08, +0.18] |
| HaWoR | 116 | 0.12 | 0.28 | +0.09 [+0.04, +0.15] |
| Head-camera lifter (ours) | 68 | 0.09 | 0.24 | +0.12 [+0.06, +0.18] |
Full results table
| Label source | label error (mm) | imitation | ours − this | with 25% / 50% of demos | tracking + RL | ours − this |
|---|---|---|---|---|---|---|
| Reference hands | 0.0 | 0.29 [0.24, 0.36] | −0.09 [−0.14, −0.03] | 0.09 / 0.15 | 0.46 [0.38, 0.54] | −0.05 [−0.12, +0.03] |
| Ours: fixed cameras | 28.4 | 0.21 [0.16, 0.26] | – | 0.08 / 0.14 | 0.41 [0.34, 0.49] | – |
| WiLoR + given head poses | 73.0 | 0.08 [0.06, 0.11] | +0.13 [+0.08, +0.18] | 0.03 / 0.05 | 0.25 [0.19, 0.31] | +0.16 [+0.08, +0.24] |
| HaWoR, given head poses | 116.2 | 0.12 [0.09, 0.15] | +0.09 [+0.04, +0.15] | 0.03 / 0.06 | 0.28 [0.21, 0.35] | +0.13 [+0.05, +0.21] |
| Ours, head camera only: lifter | 67.8 | 0.09 [0.06, 0.13] | +0.12 [+0.06, +0.18] | 0.04 / 0.08 | 0.24 [0.17, 0.30] | +0.18 [+0.11, +0.25] |
| MediaPipe, head camera | 90.9 | 0.03 [0.01, 0.05] | +0.18 [+0.13, +0.24] | 0.01 / 0.02 | – | – |
| Combination: ours + head camera | 35.8 | 0.23 [0.18, 0.28] | −0.02 [−0.06, +0.03] | 0.07 / 0.15 | 0.39 [0.32, 0.47] | +0.02 [−0.04, +0.08] |
| Combination, post-hoc variant | 35.7 | 0.23 [0.18, 0.28] | −0.02 [−0.06, +0.02] | 0.07 / 0.14 | 0.35 [0.28, 0.42] | +0.07 [+0.01, +0.12] |
| Reference + 25 mm drift | 22.0 | 0.18 [0.14, 0.23] | +0.03 [−0.03, +0.08] | 0.07 / 0.12 | 0.36 [0.27, 0.43] | +0.06 [−0.03, +0.14] |
| Reference + 50 mm drift | 43.7 | 0.12 [0.09, 0.15] | +0.09 [+0.04, +0.15] | 0.06 / 0.09 | – | – |
OakInk2 pick-and-place, 123 episodes × 6 held-out start poses × 5 training seeds. Imitation and tracking + RL success with 95% intervals over episodes; “ours − this” is paired. The drift rows add smooth drift to the reference labels.
OakInk2: sliding an object
On 150 OakInk2 slide episodes, imitation policies trained on our labels succeed in 0.31 of held-out tests, against 0.12 to 0.20 for head-camera labels (MediaPipe to our head-camera lifter); ours − WiLoR is +0.15, 95% CI [+0.09, +0.20]. Our labels are level with the motion-capture labels (0.33; ours − motion capture −0.02, 95% CI [−0.07, +0.02]). With tracking and reinforcement learning, ours reaches 0.42 against 0.24 to 0.33 for head-camera labels and 0.45 for motion capture.
imitationtracking + reinforcement learning95% confidence interval
| Labels | error (mm) | imitation | tracking + RL | ours − this |
|---|---|---|---|---|
| Reference | – | 0.33 | 0.45 | −0.02 [−0.07, +0.02] |
| Ours | 17 | 0.31 | 0.42 | – |
| Combination | 31 | 0.32 | 0.42 | −0.02 [−0.06, +0.02] |
| WiLoR | 78 | 0.16 | 0.24 | +0.15 [+0.09, +0.20] |
| HaWoR | 101 | 0.15 | 0.27 | +0.15 [+0.10, +0.21] |
| Head-camera lifter (ours) | 64 | 0.20 | 0.33 | +0.11 [+0.07, +0.15] |
Full results table
| Label source | label error (mm) | imitation | ours − this | with 25% / 50% of demos | tracking + RL | ours − this |
|---|---|---|---|---|---|---|
| Reference hands | 0.0 | 0.33 [0.28, 0.38] | −0.02 [−0.07, +0.02] | – | 0.45 [0.39, 0.52] | −0.04 [−0.11, +0.03] |
| Ours: fixed cameras | 16.9 | 0.31 [0.26, 0.36] | – | – | 0.42 [0.35, 0.48] | – |
| WiLoR + given head poses | 78.2 | 0.16 [0.12, 0.20] | +0.15 [+0.09, +0.20] | – | 0.24 [0.18, 0.29] | +0.18 [+0.11, +0.25] |
| HaWoR, given head poses | 101.1 | 0.15 [0.12, 0.19] | +0.15 [+0.10, +0.21] | – | 0.27 [0.21, 0.33] | +0.14 [+0.07, +0.22] |
| Ours, head camera only: lifter | 63.8 | 0.20 [0.16, 0.24] | +0.11 [+0.07, +0.15] | – | 0.33 [0.26, 0.40] | +0.09 [+0.01, +0.17] |
| MediaPipe, head camera | 86.4 | 0.12 [0.09, 0.16] | +0.18 [+0.14, +0.24] | – | – | – |
| Combination: ours + head camera | 30.9 | 0.32 [0.28, 0.37] | −0.02 [−0.06, +0.02] | – | 0.42 [0.36, 0.49] | −0.01 [−0.07, +0.05] |
| Combination, post-hoc variant | 42.2 | 0.31 [0.26, 0.36] | 0.00 [−0.04, +0.04] | – | 0.41 [0.34, 0.48] | 0.00 [−0.07, +0.07] |
| Reference + 25 mm drift | 21.7 | 0.26 [0.21, 0.30] | +0.05 [0.00, +0.10] | – | 0.39 [0.33, 0.46] | +0.02 [−0.06, +0.10] |
| Reference + 50 mm drift | 43.2 | 0.15 [0.12, 0.18] | +0.15 [+0.10, +0.20] | – | – | – |
OakInk2 slide, 150 episodes × 6 held-out start poses × 5 training seeds. Imitation and tracking + RL success with 95% intervals over episodes; “ours − this” is paired. The drift rows add smooth drift to the reference labels.
OakInk2: lift-and-return
On 36 OakInk2 lift-and-return episodes there is no clear difference between our labels and WiLoR’s: imitation policies succeed in 0.20 of held-out tests with ours and 0.18 with WiLoR’s (ours − WiLoR +0.02, 95% CI [−0.08, +0.12]). Ours sits well below the motion-capture labels (0.36; ours − motion capture −0.16, 95% CI [−0.27, −0.07]), and so does every head-camera source. With tracking and reinforcement learning the picture is the same: 0.32 for ours, 0.29 for WiLoR’s and 0.50 for motion capture. With so few episodes the intervals are wide.
imitationtracking + reinforcement learning95% confidence interval
| Labels | error (mm) | imitation | tracking + RL | ours − this |
|---|---|---|---|---|
| Reference | – | 0.36 | 0.50 | −0.16 [−0.27, −0.07] |
| Ours | 21 | 0.20 | 0.32 | – |
| Combination | 38 | 0.23 | 0.34 | −0.04 [−0.10, +0.03] |
| WiLoR | 83 | 0.18 | 0.29 | +0.02 [−0.08, +0.12] |
| HaWoR | 164 | 0.14 | 0.28 | +0.06 [−0.03, +0.16] |
| Head-camera lifter (ours) | 78 | 0.13 | 0.25 | +0.07 [−0.04, +0.19] |
Full results table
| Label source | label error (mm) | imitation | ours − this | with 25% / 50% of demos | tracking + RL | ours − this |
|---|---|---|---|---|---|---|
| Reference hands | 0.0 | 0.36 [0.26, 0.47] | −0.16 [−0.27, −0.07] | 0.14 / 0.28 | 0.50 [0.37, 0.63] | −0.18 [−0.31, −0.04] |
| Ours: fixed cameras | 20.5 | 0.20 [0.11, 0.30] | – | 0.12 / 0.16 | 0.32 [0.20, 0.45] | – |
| WiLoR + given head poses | 82.9 | 0.18 [0.12, 0.25] | +0.02 [−0.08, +0.12] | 0.19 / 0.18 | 0.29 [0.19, 0.39] | +0.04 [−0.11, +0.18] |
| HaWoR, given head poses | 163.8 | 0.14 [0.07, 0.21] | +0.06 [−0.03, +0.16] | 0.10 / 0.14 | 0.28 [0.16, 0.42] | +0.05 [−0.12, +0.21] |
| Ours, head camera only: lifter | 78.3 | 0.13 [0.06, 0.21] | +0.07 [−0.04, +0.19] | 0.13 / 0.11 | 0.25 [0.13, 0.38] | +0.07 [−0.11, +0.27] |
| MediaPipe, head camera | 107.3 | 0.06 [0.03, 0.10] | +0.14 [+0.05, +0.24] | 0.04 / 0.04 | – | – |
| Combination: ours + head camera | 38.3 | 0.23 [0.14, 0.33] | −0.04 [−0.10, +0.03] | 0.18 / 0.20 | 0.34 [0.22, 0.47] | −0.02 [−0.15, +0.11] |
| Combination, post-hoc variant | 40.3 | 0.20 [0.12, 0.29] | −0.01 [−0.06, +0.06] | 0.19 / 0.24 | 0.31 [0.19, 0.44] | +0.01 [−0.15, +0.17] |
| Reference + 25 mm drift | 22.5 | 0.27 [0.19, 0.37] | −0.08 [−0.19, +0.03] | 0.15 / 0.20 | 0.43 [0.30, 0.56] | −0.10 [−0.26, +0.06] |
| Reference + 50 mm drift | 45.0 | 0.15 [0.09, 0.22] | +0.05 [−0.04, +0.14] | 0.11 / 0.16 | – | – |
OakInk2 lift-and-return, 36 episodes × 6 held-out start poses × 5 training seeds. Imitation and tracking + RL success with 95% intervals over episodes; “ours − this” is paired. The drift rows add smooth drift to the reference labels.
HO-Cap: reorienting an object
On 41 reorientation episodes, imitation policies trained on our labels succeed in 0.29 of held-out tests, level with the reference labels (0.27), against 0.03 to 0.10 for head-camera labels (MediaPipe to our head-camera lifter); ours leads each head-camera source by 0.19 to 0.26, every interval above zero.
imitationtracking + reinforcement learning95% confidence interval
| Labels | error (mm) | imitation | tracking + RL | ours − this |
|---|---|---|---|---|
| Reference | – | 0.27 | 0.60 | +0.02 [−0.03, +0.07] |
| Ours | 8 | 0.29 | 0.47 | – |
| WiLoR | 63 | 0.08 | 0.28 | +0.21 [+0.11, +0.32] |
| WiLoR + SLAM | 63 | 0.07 | 0.15 | +0.22 [+0.12, +0.33] |
| HaWoR | 63 | 0.07 | 0.12 | +0.22 [+0.13, +0.31] |
| Head-camera lifter (ours) | 51 | 0.10 | 0.33 | +0.19 [+0.11, +0.28] |
Full results table
| Label source | label error (mm) | imitation | ours − this | with 25% / 50% of demos | tracking + RL | ours − this |
|---|---|---|---|---|---|---|
| Reference hands | 0.0 | 0.27 [0.19, 0.36] | +0.02 [−0.03, +0.07] | 0.16 / 0.20 | 0.60 [0.46, 0.73] | −0.13 [−0.24, −0.02] |
| Ours: fixed cameras | 8.2 | 0.29 [0.19, 0.40] | – | 0.19 / 0.23 | 0.47 [0.33, 0.61] | – |
| WiLoR + given head poses | 63.2 | 0.08 [0.05, 0.11] | +0.21 [+0.11, +0.32] | 0.05 / 0.06 | 0.28 [0.15, 0.40] | +0.20 [+0.05, +0.35] |
| WiLoR + HaWoR’s SLAM | 63.0 | 0.07 [0.04, 0.12] | +0.22 [+0.12, +0.33] | 0.05 / 0.07 | 0.15 [0.07, 0.24] | +0.32 [+0.18, +0.46] |
| HaWoR, given head poses | 62.7 | 0.07 [0.04, 0.11] | +0.22 [+0.13, +0.31] | 0.08 / 0.08 | 0.12 [0.05, 0.21] | +0.35 [+0.21, +0.49] |
| HaWoR, own SLAM | 64.3 | 0.09 [0.04, 0.14] | +0.21 [+0.12, +0.30] | 0.07 / 0.07 | – | – |
| Ours, head camera only: lifter | 51.4 | 0.10 [0.05, 0.16] | +0.19 [+0.11, +0.28] | 0.09 / 0.11 | 0.33 [0.20, 0.46] | +0.14 [0.00, +0.28] |
| MediaPipe, head camera | 114.8 | 0.03 [0.01, 0.06] | +0.26 [+0.17, +0.37] | 0.06 / 0.05 | – | – |
| Reference + 25 mm drift | 21.3 | 0.26 [0.18, 0.36] | +0.03 [−0.06, +0.12] | 0.16 / 0.22 | 0.53 [0.39, 0.67] | −0.06 [−0.15, +0.03] |
| Reference + 50 mm drift | 41.6 | 0.15 [0.09, 0.23] | +0.14 [+0.04, +0.25] | 0.08 / 0.11 | 0.30 [0.18, 0.42] | +0.17 [+0.02, +0.33] |
Reorientation, 41 episodes × 6 held-out start poses × 5 training seeds. Imitation and tracking + RL success with 95% intervals over episodes; “ours − this” is paired. The drift rows add smooth drift to the reference labels.
HO-Cap: lift-and-return
On 14 lift-and-return episodes, our labels come in below the reference (0.44 against 0.57; −0.13, 95% CI [−0.31, +0.01], an interval that includes zero) and lead WiLoR’s by +0.38 [+0.18, +0.58].
imitationtracking + reinforcement learning95% confidence interval
| Labels | error (mm) | imitation | tracking + RL | ours − this |
|---|---|---|---|---|
| Reference | – | 0.57 | 0.74 | −0.13 [−0.31, +0.01] |
| Ours | 8 | 0.44 | 0.69 | – |
| WiLoR | 60 | 0.06 | 0.36 | +0.38 [+0.18, +0.58] |
| WiLoR + SLAM | 66 | 0.11 | 0.43 | +0.33 [+0.09, +0.56] |
| HaWoR | 59 | 0.16 | 0.40 | +0.28 [+0.04, +0.52] |
| Head-camera lifter (ours) | 50 | 0.22 | 0.57 | +0.21 [−0.05, +0.46] |
Full results table
| Label source | label error (mm) | imitation | ours − this | with 25% / 50% of demos | tracking + RL | ours − this |
|---|---|---|---|---|---|---|
| Reference hands | 0.0 | 0.57 [0.36, 0.76] | −0.13 [−0.31, +0.01] | 0.31 / 0.33 | 0.74 [0.52, 0.93] | −0.05 [−0.21, +0.07] |
| Ours: fixed cameras | 8.2 | 0.44 [0.24, 0.64] | – | 0.20 / 0.25 | 0.69 [0.45, 0.93] | – |
| WiLoR + given head poses | 60.0 | 0.06 [0.01, 0.12] | +0.38 [+0.18, +0.58] | 0.06 / 0.08 | 0.36 [0.17, 0.57] | +0.33 [+0.17, +0.52] |
| WiLoR + HaWoR’s SLAM | 66.0 | 0.11 [0.03, 0.21] | +0.33 [+0.09, +0.56] | 0.05 / 0.06 | 0.43 [0.21, 0.64] | +0.26 [+0.10, +0.45] |
| HaWoR, given head poses | 58.6 | 0.16 [0.03, 0.33] | +0.28 [+0.04, +0.52] | 0.07 / 0.13 | 0.40 [0.19, 0.64] | +0.29 [+0.02, +0.55] |
| HaWoR, own SLAM | 61.4 | 0.19 [0.04, 0.38] | +0.25 [−0.03, +0.50] | 0.10 / 0.14 | – | – |
| Ours, head camera only: lifter | 49.8 | 0.22 [0.07, 0.40] | +0.21 [−0.05, +0.46] | 0.14 / 0.15 | 0.57 [0.29, 0.79] | +0.12 [−0.14, +0.40] |
| MediaPipe, head camera | 118.2 | 0.04 [0.01, 0.07] | +0.40 [+0.22, +0.58] | 0.01 / 0.02 | – | – |
| Reference + 25 mm drift | 21.1 | 0.38 [0.19, 0.59] | +0.06 [−0.22, +0.34] | 0.27 / 0.38 | 0.74 [0.52, 0.93] | −0.05 [−0.26, +0.17] |
| Reference + 50 mm drift | 42.5 | 0.26 [0.11, 0.43] | +0.18 [−0.06, +0.40] | 0.11 / 0.17 | 0.50 [0.24, 0.74] | +0.19 [−0.07, +0.45] |
Lift-and-return, 14 episodes × 6 held-out start poses × 5 training seeds. Imitation and tracking + RL success with 95% intervals over episodes; “ours − this” is paired. The drift rows add smooth drift to the reference labels.
HO-Cap: pouring
Pouring (15 episodes) is too hard for imitation to separate the sources, with the reference labels at only 0.14; with reinforcement learning, ours reaches 0.53 against 0.20 for WiLoR (+0.33, 95% CI [+0.07, +0.60]).
imitationtracking + reinforcement learning95% confidence interval
| Labels | error (mm) | imitation | tracking + RL | ours − this |
|---|---|---|---|---|
| Reference | – | 0.14 | 0.44 | −0.01 [−0.11, +0.06] |
| Ours | 10 | 0.13 | 0.53 | – |
| WiLoR | 61 | 0.05 | 0.20 | +0.08 [−0.01, +0.17] |
| WiLoR + SLAM | 60 | 0.06 | 0.20 | +0.07 [−0.02, +0.16] |
| HaWoR | 69 | 0.02 | 0.13 | +0.11 [+0.05, +0.19] |
| Head-camera lifter (ours) | 50 | 0.10 | 0.27 | +0.03 [−0.06, +0.11] |
Full results table
| Label source | label error (mm) | imitation | ours − this | with 25% / 50% of demos | tracking + RL | ours − this |
|---|---|---|---|---|---|---|
| Reference hands | 0.0 | 0.14 [0.04, 0.29] | −0.01 [−0.11, +0.06] | 0.12 / 0.04 | 0.44 [0.24, 0.67] | +0.09 [−0.13, +0.31] |
| Ours: fixed cameras | 9.5 | 0.13 [0.07, 0.21] | – | 0.10 / 0.06 | 0.53 [0.31, 0.76] | – |
| WiLoR + given head poses | 61.3 | 0.05 [0.01, 0.11] | +0.08 [−0.01, +0.17] | 0.06 / 0.05 | 0.20 [0.04, 0.38] | +0.33 [+0.07, +0.60] |
| WiLoR + HaWoR’s SLAM | 60.1 | 0.06 [0.02, 0.12] | +0.07 [−0.02, +0.16] | 0.08 / 0.04 | 0.20 [0.07, 0.38] | +0.33 [+0.07, +0.60] |
| HaWoR, given head poses | 69.0 | 0.02 [0.00, 0.03] | +0.11 [+0.05, +0.19] | 0.03 / 0.04 | 0.13 [0.02, 0.29] | +0.40 [+0.13, +0.64] |
| HaWoR, own SLAM | 64.0 | 0.11 [0.03, 0.23] | +0.02 [−0.12, +0.14] | 0.03 / 0.02 | – | – |
| Ours, head camera only: lifter | 50.2 | 0.10 [0.03, 0.19] | +0.03 [−0.06, +0.11] | 0.11 / 0.13 | 0.27 [0.07, 0.51] | +0.27 [+0.09, +0.49] |
| MediaPipe, head camera | 132.5 | 0.01 [0.00, 0.01] | +0.12 [+0.06, +0.20] | 0.00 / 0.03 | – | – |
| Reference + 25 mm drift | 21.1 | 0.22 [0.10, 0.37] | −0.09 [−0.24, +0.03] | 0.04 / 0.11 | 0.51 [0.27, 0.76] | +0.02 [−0.24, +0.31] |
| Reference + 50 mm drift | 42.9 | 0.20 [0.06, 0.38] | −0.07 [−0.22, +0.05] | 0.15 / 0.10 | 0.42 [0.20, 0.67] | +0.11 [−0.13, +0.36] |
Pouring, 15 episodes × 6 held-out start poses × 5 training seeds. Imitation and tracking + RL success with 95% intervals over episodes; “ours − this” is paired. The drift rows add smooth drift to the reference labels.
With fewer demos
On OakInk2 pick-and-place, our labels lead WiLoR’s and HaWoR’s at every share of the demos: 0.08 against at most 0.03 with a quarter, 0.21 against at most 0.12 with all of them. With a quarter of the HO-Cap reorientation demos our labels reach 0.19, and no head-camera source gets above 0.10 with all of them. On the lift-and-return tasks and on pouring, where every source is noisier, the curves sit closer together.
oursreference, WiLoR, HaWoRother label sources
More reinforcement learning
On OakInk2 pick-and-place, with the same compute for every source, success rises from 0.34 at 24 rollouts per episode to 0.47 at 384 for our labels, from 0.17 to 0.29 for WiLoR’s and from 0.21 to 0.31 for HaWoR’s; the motion-capture labels reach 0.51. The gap does not close with more compute: ours minus WiLoR goes from +0.17 to +0.18, and ours minus HaWoR from +0.13 to +0.16.
success on held-out start poses after that many rollouts per episode
On HO-Cap reorientation, longer reinforcement learning levels off at different heights: at 384 rollouts per episode, 0.61 for the reference labels, 0.53 for ours, 0.30 for WiLoR’s and 0.16 for HaWoR’s (ours [0.39, 0.67] against WiLoR’s [0.19, 0.43]).
success on held-out start poses after that many rollouts per episode
Synthetic demos from a few real ones
We expanded a tenth of the reorientation demos a hundredfold into synthetic demos, re-posed or with varied objects, table and clutter. With our labels these reach 0.11 and 0.09, against 0.29 from all the real demos: they succeed on the seed episodes (0.55) and not on the rest (0.06). Nor do they lift our labels above WiLoR’s full set of real demos (+0.03 [−0.03, +0.09] re-posed, +0.01 [−0.04, +0.07] with varied scenes).
Generation cost did separate our labels from the head-camera ones. A synthetic demo is kept only if it succeeds in simulation, and keeping 1,000 from a quarter of the demos took 2,160 attempts with our labels, against 7,008 with WiLoR’s and 9,504 with HaWoR’s, 3 to 4 times fewer (3,800, 11,720 and 16,360 with varied scenes).
Credits and licences
- OakInk2: Zhan et al., “OakInk2: A Dataset of Bimanual Hands-Object Manipulation in Complex Task Completion”, CVPR 2024 (arXiv 2403.19417). CC BY-SA 4.0.
- HO-Cap: Wang et al., “HO-Cap: A Capture System and Dataset for 3D Reconstruction and Pose Tracking of Hand-Object Interaction,” NeurIPS 2025 Datasets and Benchmarks Track (paper, project page). CC BY 4.0.
- HaWoR: Zhang, Deng, Ma and Potamias, “HaWoR: World-Space Hand Motion Reconstruction from Egocentric Videos”, CVPR 2025 (arXiv 2501.02973). Code and weights used for evaluation only, under their licence.
- WiLoR: Potamias et al., “WiLoR: End-to-end 3D Hand Localization and Reconstruction in-the-wild”, CVPR 2025 (arXiv 2409.12259). Evaluation only, under its licence.
- MANO: Romero, Tzionas and Black, “Embodied Hands: Modeling and Capturing Hands and Bodies Together”, SIGGRAPH Asia 2017. Used by the baselines under its research licence.
- DPVO: Teed, Lipson and Deng, “Deep Patch Visual Odometry”, NeurIPS 2023 (arXiv 2208.04726). MediaPipe Hands: Zhang et al., “MediaPipe Hands: On-device Real-time Hand Tracking” (arXiv 2006.10214), Apache-2.0. Physics: MuJoCo; robot hand: Inspire.
Benchmark split, metrics, replay and baseline runs by Autelica, 2026. Numbers on this page are generated from the evaluation files and checked against them at build time.