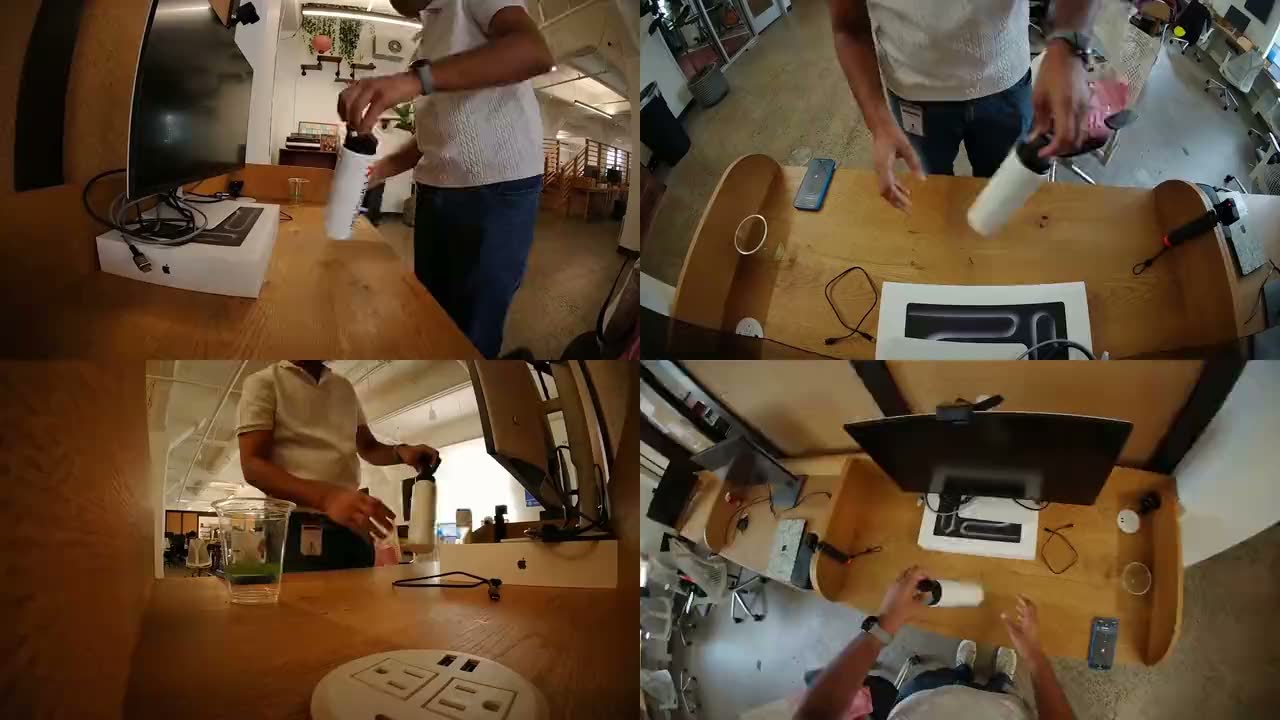
On October 19 one person sat at a desk and did eight short hand-object tasks: plugging USB-C cables into a phone, a laptop and three drones, swapping drone batteries, screwing a camera mount together, opening and typing on a laptop, stacking boxes, and opening a bottle to pour. Four consumer cameras filmed it: one on a head strap and three fixed around the desk. This page shows what came out of that footage and how accurate it is.
In short. The four cameras had no shared clock. They were synced and calibrated from the footage itself into one 3D space, with the head camera’s pose on every frame. From that come 3D hands and upper body, object masks in all four views, object poses, hand-object contacts and robot-hand retargets. Hands from the three fixed cameras agree with a left-out camera to 11.0–13.8 mm (median) on 6 of 8 tasks and 15.5–18.9 mm on the two with the most occluded grasps. With the same three-camera layout on HO-Cap, a public dataset with ground truth, the true error is 10.4 mm and the cross-view number sits about 1 mm above it.
The setup
| Place | An office desk with a laptop, a monitor and the task objects. Other people in the background whose faces could be recognised were erased from every image and video on this page, not blurred. Everything else is as filmed, in all four views of every task. |
|---|---|
| Cameras | 4 × GoPro HERO, recorded at 2.7K and 60 fps and delivered at 1080p and 30 fps: one on a head strap and three fixed (left, overhead and right) |
| Clocks | None shared. No timecode, genlock or clapper; each camera was started by hand |
| Calibration | Recovered from the footage: every camera in one 3D space with the desk, and the head camera’s pose on every frame |
| Subject | One person, who consented to capture and publication. No markers, gloves or sensors |
| Tasks | 8 tasks, each done once, 15–17 s each |
What comes out
Each task clip is delivered as one sample:
- Synced video from all four cameras on one timeline.
- Cameras: intrinsics and pose for every camera on every frame, including the moving head camera.
- 3D hands and body: 21 joints per hand and the upper body, in millimetres in one desk frame, with a quality flag on every frame.
- Object masks for the main task objects, tracked in all four views, the head camera included, with the same object id in every view and over time.
- 6-DoF object poses where the object is seen well enough, with a held-out-view check.
- Hand-object contacts: which hand touches or grips which object, from when to when.
- An error report for the clip.
- Robot-hand retargets on six of the eight tasks.
The eight tasks
Numbers are for the task span of each clip. Cross-view error is explained in the next section. Tasks marked with a play badge open in the player above.
How accurate the hands are
There is no motion-capture reference at this desk, so accuracy on this session is measured as consistency between cameras. Each fixed camera is left out in turn: the hands are rebuilt from the other two fixed cameras, projected into the left-out camera and compared with what it sees there, and the distance is converted to millimetres at the hand.
Median cross-view error over the task span, mean of the three left-out fixed cameras. The 90th percentile is 27.5–43.2 mm.
Six tasks sit at 11.0–13.8 mm. Two are higher: box stacking and bottle open and pour, at 18.9 and 15.5 mm. In both, the gripping hand is often behind the object from one or more fixed cameras: the fingers wrap a bottle or a stack of boxes rather than pinching a small part in the open.
What the cross-view number means
To translate the cross-view number into a true error, we ran the same pipeline on HO-Cap (CC BY 4.0), a public hand-object dataset with ground-truth hands, using three of its fixed cameras and its head camera in the same arrangement as here. There the true 3D joint error is 10.4 mm at the median (26.0 mm at the 90th percentile), and the cross-view number on the same frames is 11.4 mm: about 1 mm above the true error.
Every frame of every hand carries its own status, so a model can skip or down-weight what was not measured well. In the player above, the strip under the video shows it frame by frame: green where the hand is measured with high confidence, yellow with lower confidence, grey where a short gap was filled, with a tick on frames flagged as implausible.
Head camera alone vs all four
A head camera sees the hands up close, but from one viewpoint it has to guess how far away they are. We compared the best head-camera-only hands we could build against hands measured with the outside cameras.
48.4 mmbest head-camera-only hands
7.3 mmhands from the outside cameras
33.2 mmbest head-camera-only hands (95% CI 29.6–37.9)
11.0–18.9 mmour own cross-view error, for scale
Both are 21-joint hands in the head camera’s own frame, the label type head-camera datasets use. On HO-Cap the best head-camera-only method we could build lands 48.4 mm from the truth at the median, against 7.3 mm for hands measured with HO-Cap’s outside cameras (four of them here, which is why it is lower than the three-camera reading above). Most of the gap is depth: along the head camera’s line of sight the wrist is 42.4 mm off from the head camera alone and 3.2 mm with the outside cameras. On this session there is no ground truth, so the comparison is against our four-camera measurement, which has its own error of 11.0–18.9 mm.
Better labels also train a better head-camera model. A hand model trained on HO-Cap head-camera images with labels from the outside cameras is 24.3 mm from the truth on people it never saw, against 27.5 mm when trained on head-camera-only labels, and it is better for 8 of 8 people.
The cameras also help each other. The head camera sees hands the fixed cameras miss, for example when the body is between them and the hand. On HO-Cap with three fixed cameras, the share of hand-frames with a 3D measurement goes from 72% with the fixed cameras alone to 81% with the head camera added. On this session the same share goes from 70% to 82%.
Objects and contacts
Each task’s objects are tracked as masks in all four views, the head camera included, and posed in 3D, including the laptop’s lid angle. Each pose is checked against a fixed camera that was left out of it.
| Task | Object | Posed | Held-out view overlap |
|---|---|---|---|
| USB-C into a phone | phone | 97% | 0.73 |
| Mount and thumbscrew | case | 90% | 0.64 |
| USB-C into three drones | drone 1 | 88% | 0.54 |
| USB-C into three drones | drone 2 | 94% | 0.61 |
| USB-C into three drones | drone 3 | 96% | 0.56 |
| Laptop open, type, close | laptop | 71% | 0.75 |
| Drone batteries out and in | drone 1 | 97% | 0.63 |
| Drone batteries out and in | drone 2 | 87% | 0.60 |
| Drone batteries out and in | drone 3 | 99% | 0.71 |
| Drone batteries out and in | battery 1 | 66% | 0.44 |
| Drone batteries out and in | battery 2 | 60% | 0.55 |
| Drone batteries out and in | battery 3 | 100% | 0.84 |
| USB-C into a laptop | laptop | 82% | 0.79 |
| USB-C into a laptop | phone | 96% | 0.76 |
| Box stacking | box 1 | 26% | 0.42 |
| Box stacking | box 2 | 20% | 0.42 |
| Box stacking | box 3 | 47% | 0.61 |
| Box stacking | box 4 | 47% | 0.71 |
| Bottle open and pour | bottle | 76% | 0.59 |
| Bottle open and pour | cup | 98% | 0.71 |
Posed: share of task frames with a 6-DoF pose. Held-out view overlap: intersection over union between the pose projected into the left-out fixed camera and that camera’s mask (1 is perfect). Objects in a closed hand or end-on to a camera are posed less often; their masks are still tracked.
Contact labels record which hand touches which object, from when to when, and whether the contact is a grasp. They appear as the bottom row of the strip in the player.
The desk in 3D
The whole session in one 3D scene: the desk and objects rebuilt from the footage, the three fixed cameras, the head camera’s path, the tracked objects and both hands with their recent paths. Drag to orbit, scroll or pinch to zoom, and pick a task on the timeline.
Robot hands
The measured hands are retargeted to four robot hands: Unitree Dex3, Inspire, LEAP and Allegro. Retargets come with six of the eight tasks. They work best on the pinch and insertion tasks, where the fingers stay visible. On the mount screw, the robot hand opens and closes with the person’s right hand at an F1 score of 0.98–0.99 across the four hands. The robot’s grip width follows the person’s to within 10 mm when retargeted from our hands and 15.5 mm from the best head-camera-only hands.
Grasps where the hand is hidden behind the object, as in the box stacking and the bottle-lid twist, are not good enough to retarget yet and are left out.
Limits and next steps
- One person, one session. Every task was done once, by one person, at one desk.
- No ground truth at this desk. Accuracy here is cross-view consistency; the true-error reading comes from HO-Cap with the same camera layout.
- Masks are checked by agreement between views, not by hand.
- Occluded grasps. The bottle and the box stacking have the highest error.
- No folding yet. It is planned for the next session.
Next: folding tasks, three to five repeats of every task, more people, and a session next to a motion-capture reference for true error on this rig.
HO-Cap: public hand-object dataset (CC BY 4.0), used for evaluation. Robot hands are shown in simulation.